Standby nodes differ from read-only nodes, which provide geographically distinct horizontal read scaling.
How to Add Standby Nodes to PostgreSQL Database Clusters
Last verified 19 Aug 2026
PostgreSQL is an open source, object-relational database built for extensibility, data integrity, and speed. Its concurrency support makes it fully ACID-compliant, and it supports dynamic loading and catalog-driven operations to let users customize its data types, functions, and more.
In a database cluster, standby nodes maintain a copy of the primary node. If the primary node fails, a standby node is automatically promoted to replace it. You can optionally send read traffic to standby nodes. See Use Standby Nodes for Reads.
Clusters can have up to two standby nodes. At least one standby node is necessary for a high availability cluster configuration.
You can add standby nodes during cluster creation in the cluster configuration section of the create page.
You can also add standby nodes to an existing database cluster. From the Databases page, click the cluster to go to its Overview page, then click the Settings tab.
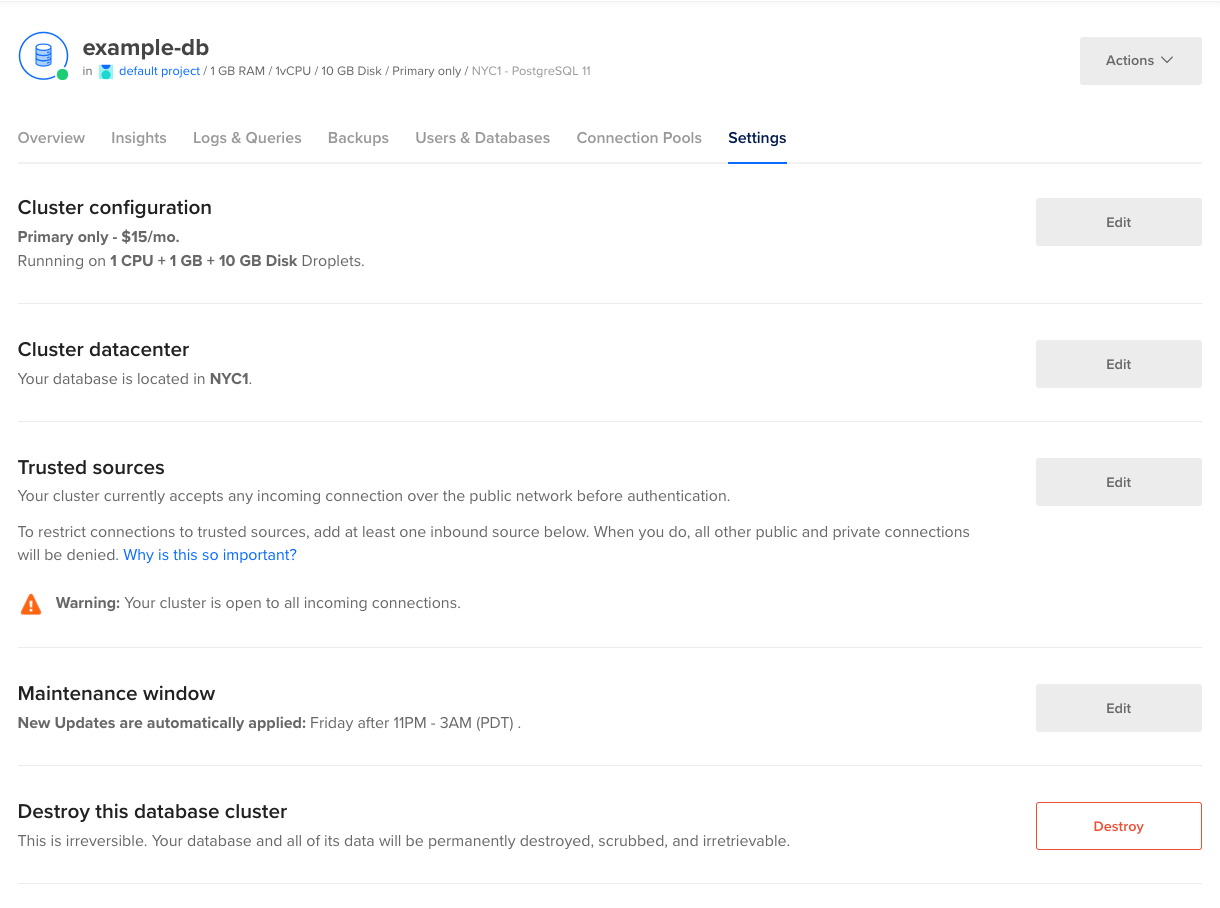
On the Settings page, in the Cluster configuration section, click Edit. Open the Standby Nodes drop-down and choose the number of standby nodes.
Due to the memory requirements of replication, standby nodes are only supported for plans with 2 GB of RAM or more.
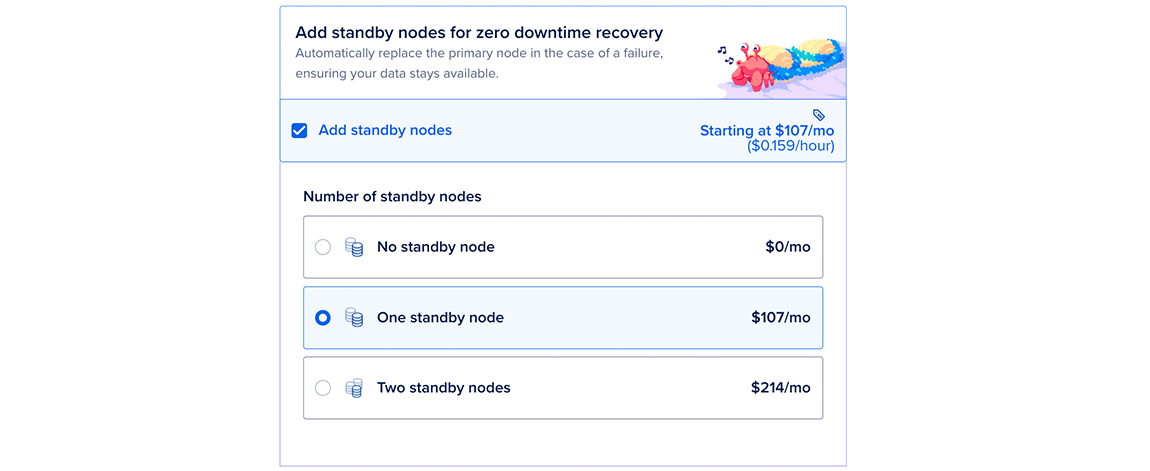
When you’re done, click Save to immediately provision the standby nodes. The time to complete varies depending on the size of the primary node and its data, but we recommend allowing at least 5 minutes.
Use Standby Nodes for Reads
Standby nodes primarily provide high availability. If the primary node fails, a standby node is automatically promoted to replace it.
You can also send read traffic to standby nodes to improve cluster performance. However, doing so can overwhelm standby nodes and leave them unable to replace the primary during a failure. We recommend sending read traffic to read-only nodes instead.
To use standby nodes for reads, you can find the standby nodes’ hostname via the API.
And you can find the standby nodes’ IP addresses by querying DNS. To connect to the standby node, add the replica- prefix to the primary cluster connection URL. For example:
dig +short A replica-postgresql-test-do-user-4915853-0.db.ondigitalocean.com
203.0.113.10
203.0.113.11
Traffic you send to multiple standby nodes is not load balanced. In order to load balance this traffic, you can either use a client that does it natively or look up the IPs with a tool such as dig.